Indexing documents for an agent: the mistakes I keep seeing
Most inaccurate agent answers are born at indexing, before the model touches anything. The document-processing mistakes I see most often.
Most inaccurate answers of an AI agent are born at indexing. Before the model has touched anything. A chunk cut in half stays cut in half, whatever the model does next.
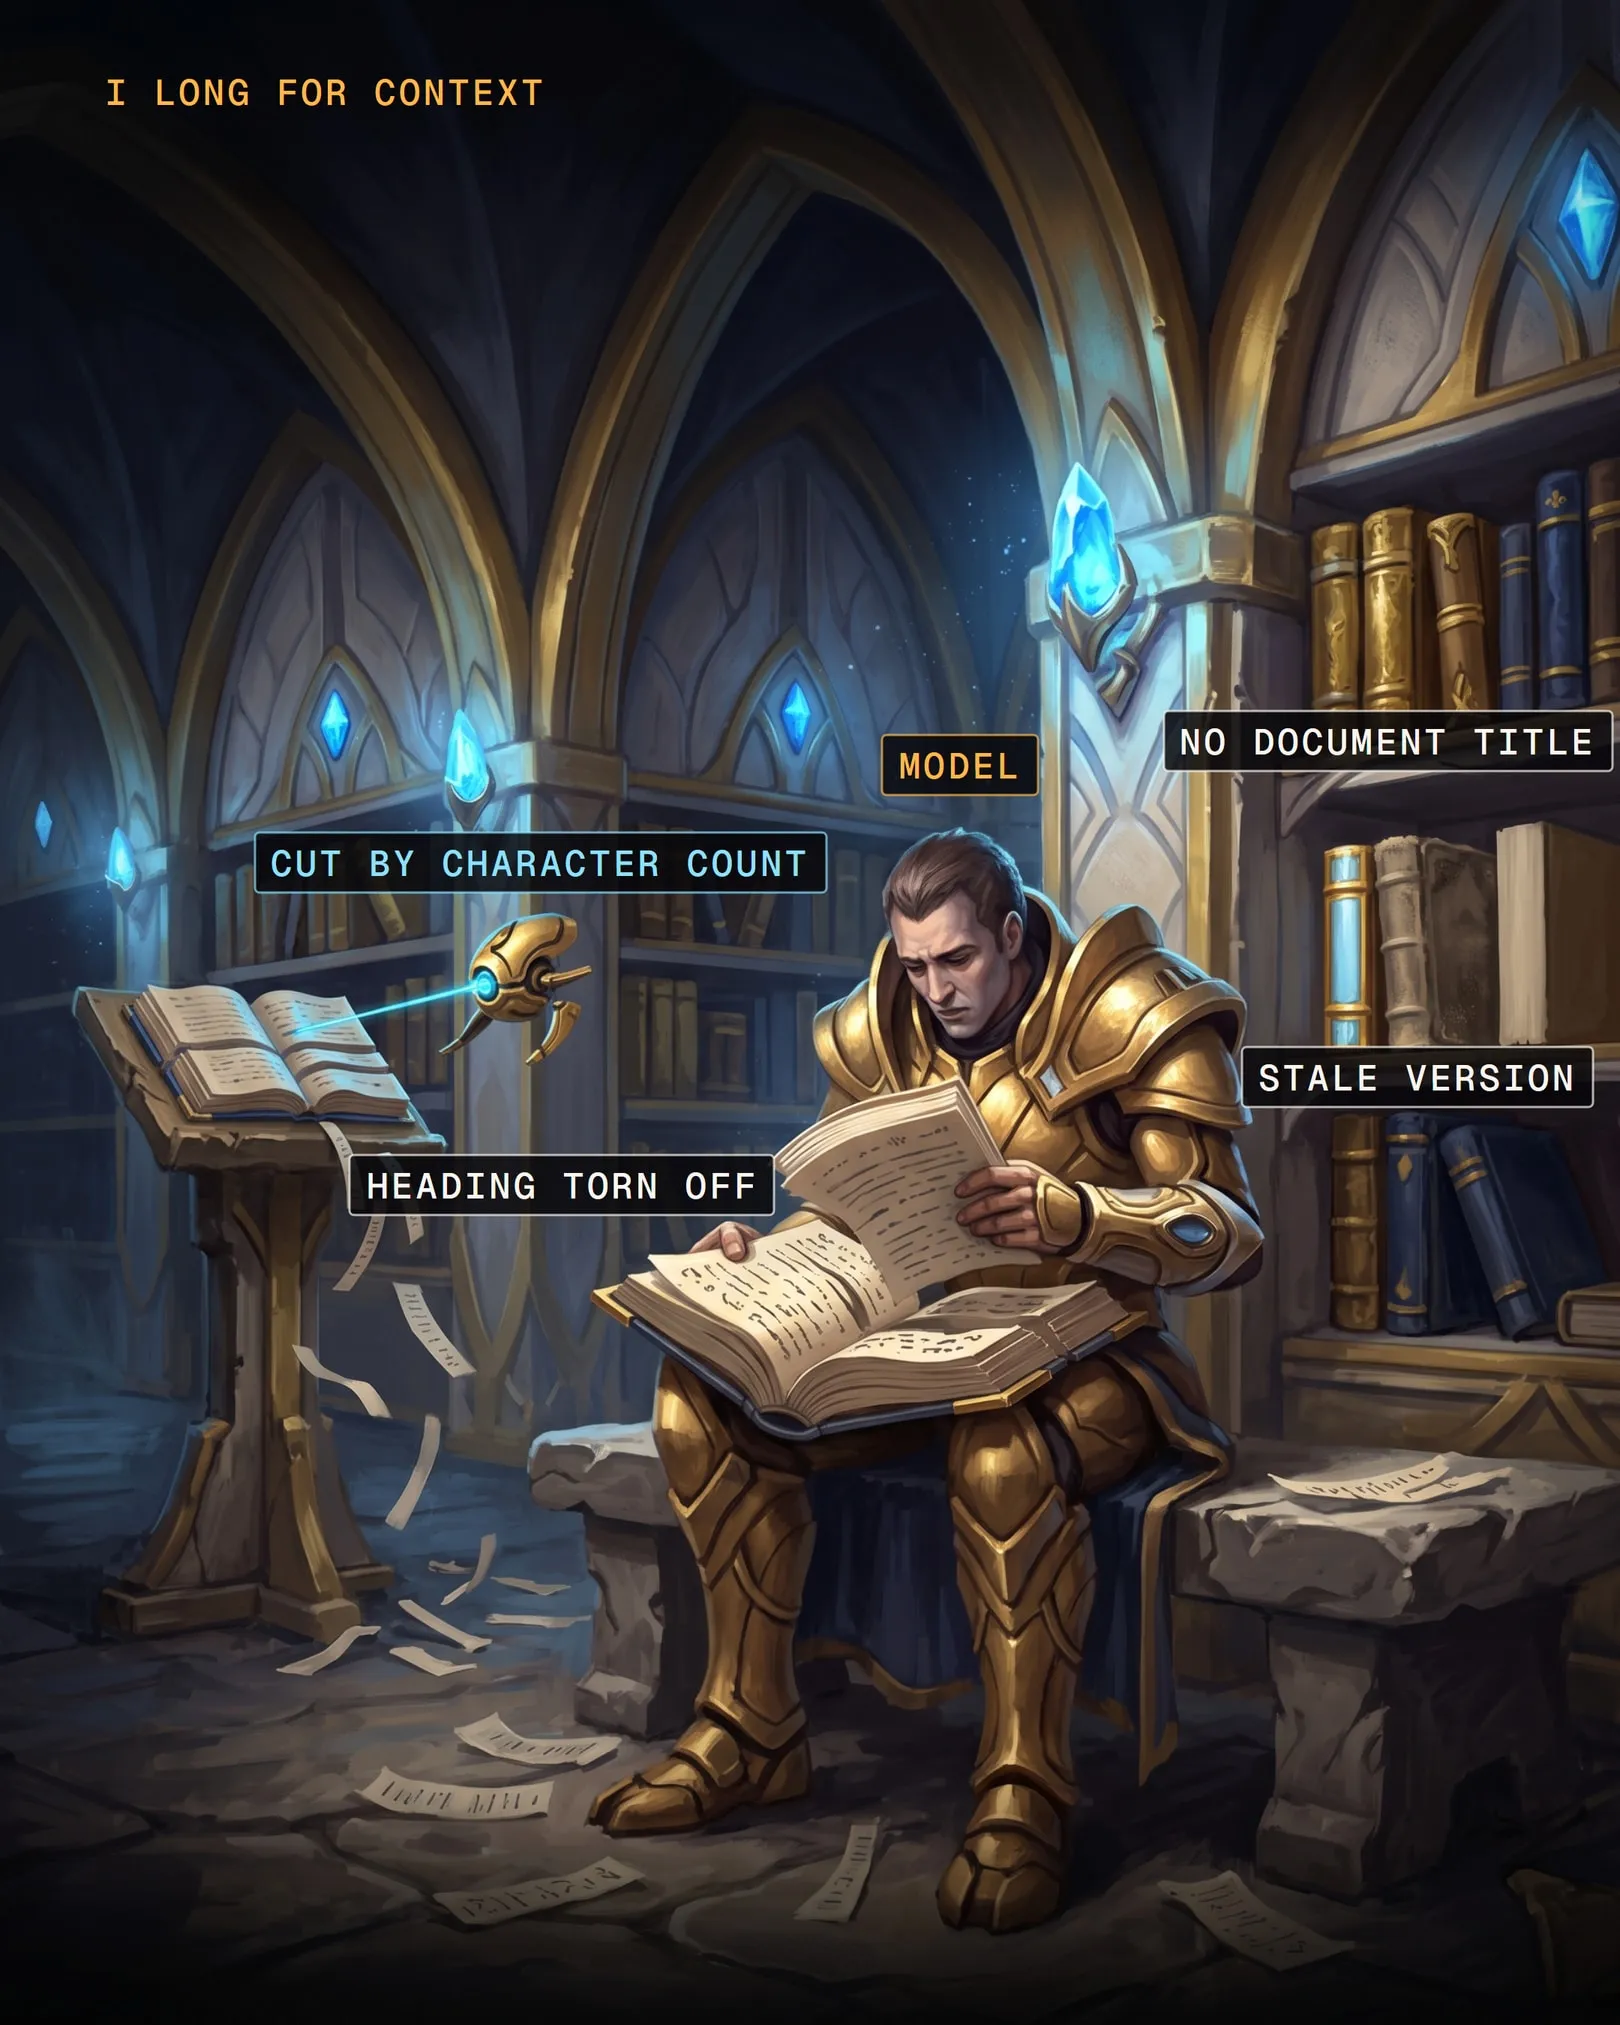
The mistakes I see most often:
Extraction
- PDF headers, footers and page numbers land in every chunk. Columns are read straight across the page.
- Tables and diagrams inside images are skipped.
Chunking
- Cutting by character count. Words get split, a heading ends one chunk while its content starts the next. Chunk by document structure instead.
- Tables as plain text. A long table is cut mid-row, and the second half has no header. Cut by rows, repeat the header.
Context
- A chunk doesn’t know its document. The title sits only in the first chunk. Put “document › section” in front of every chunk, into both the vector and the keywords.
- The same disclaimer at the top of every document. The first chunks look alike, and search can’t tell the documents apart.
Upkeep
- Duplicates and stale versions sit next to the current one.
- Updates are loaded by hand: someone uploads the new version, someone removes the old one. It quickly turns into an annoying routine, and the index falls behind. Plan automatic sync from the source from day one.
- Access rights get lost on the way in. The agent quotes a document the user can’t open.
Process
- Bending documents around the tool: rewriting them into short paragraphs to suit the chunker. Fix the chunker instead.
- The index goes unchecked. Teams read answers, not chunks. Count the defects in the chunks: words cut in half, headings torn from their content, chunks without a document title.